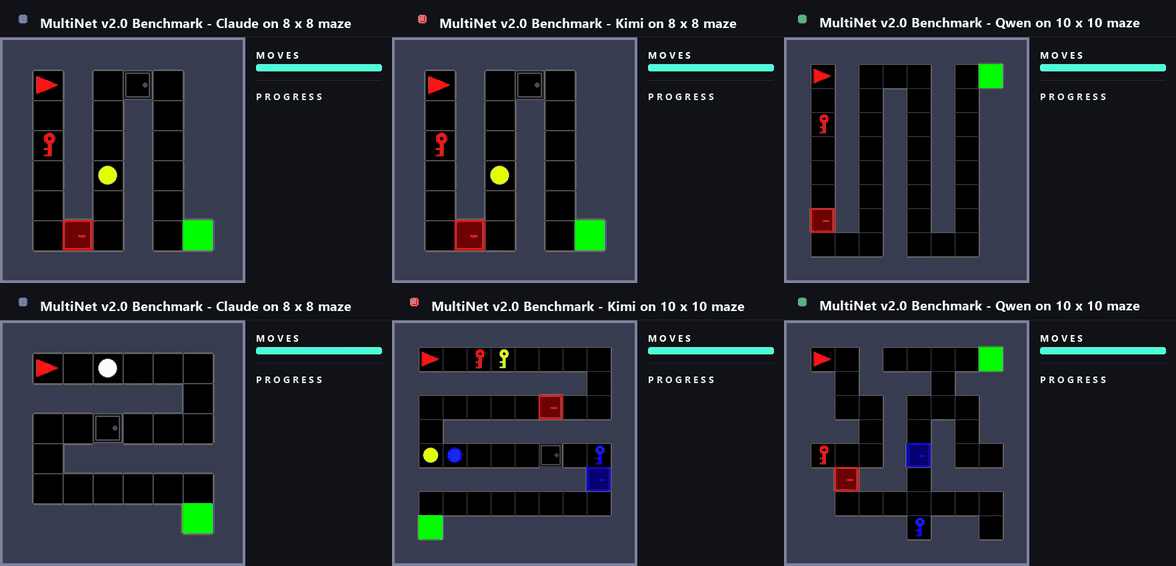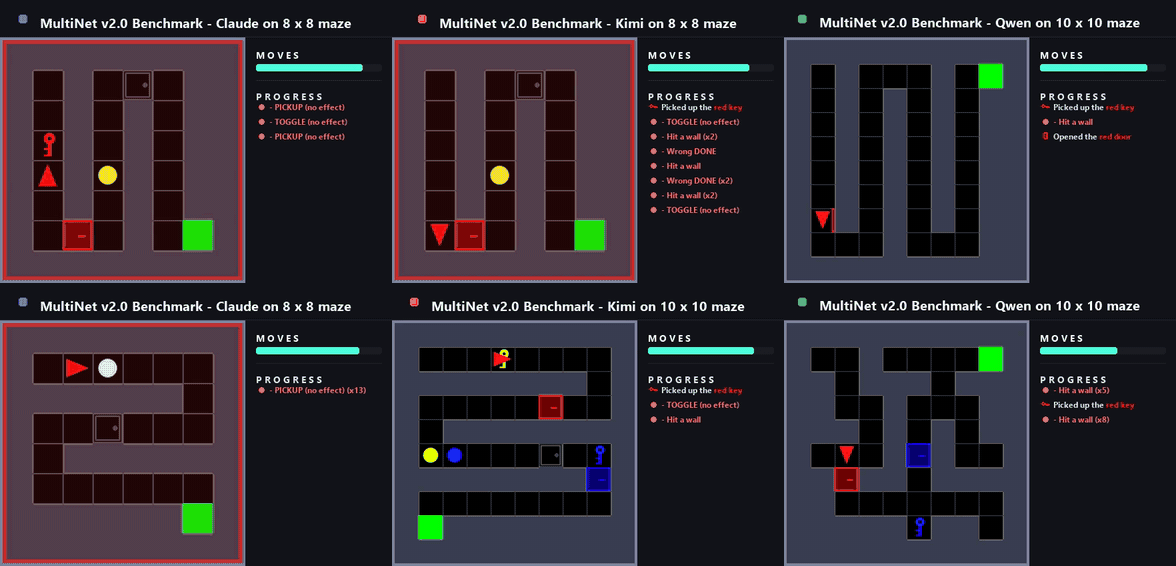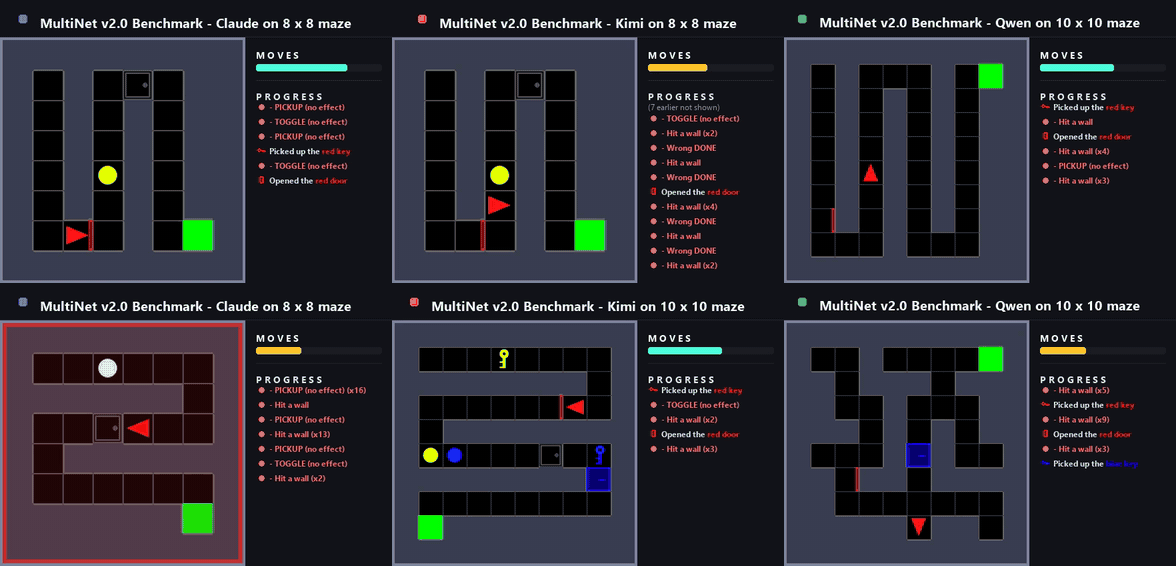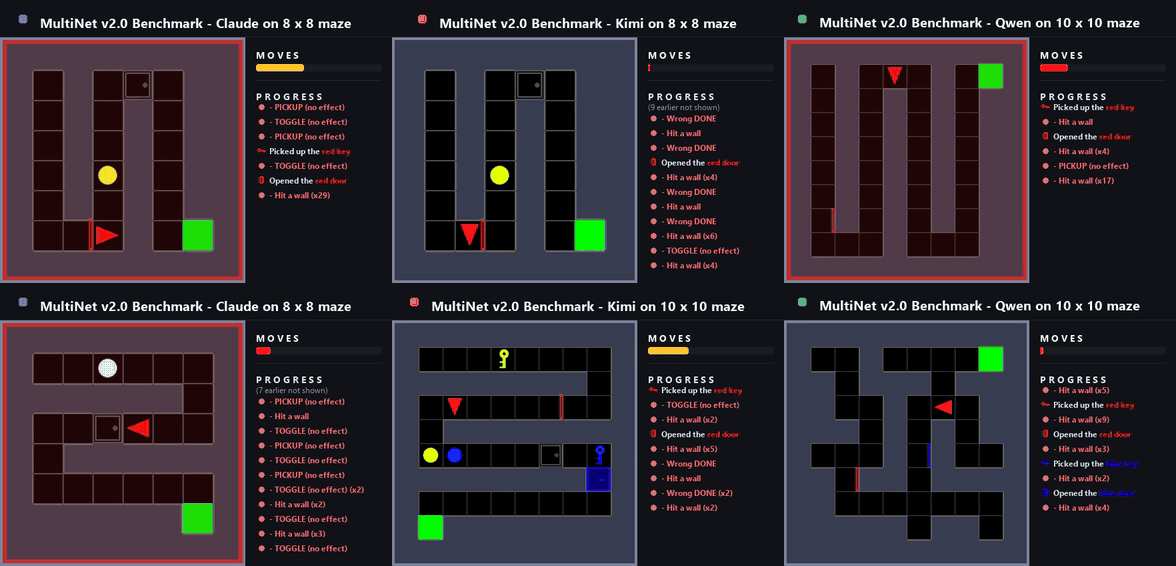
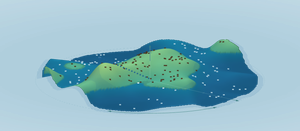
Frontier models are now used for browsing, self-driving, assembly work and tabletop manipulation tasks. Their performance on these domains and deployment decisions rely on the benchmark scores labs report. However, a benchmark mean hides how much a model's success varies across tasks. We call a profile jagged when a model's success rate swings widely across tasks the benchmark reports under one number.
Recent work measures agent reliability, and holistic leaderboards report the dispersion a headline number drops. Those results commonly cover text-centric agents on digital tasks, or report that dispersion at the level of the benchmark or task category average. Because agent behavior is learned rather than specified, its competence has to be measured by testing, on the tasks users run rather than as one benchmark average. The task category a model is deployed on affects its reliability about as much as the choice of model.